Adapted from Prompting Guide: DSP — https://www.promptingguide.ai/techniques/dsp
Introduction
Getting a large language model to generate a specific style or tone of output can be challenging with standard prompts. Directional Stimulus Prompting (DSP), proposed by Li et al. (2023), introduces a two-model system to bridge this gap.
How DSP Works
The core idea of DSP is to use a small, tunable policy LM to generate a "stimulus" or "hint" for every input. This stimulus is then appended to the original prompt to guide a much larger, frozen black-box LLM (like GPT-4).
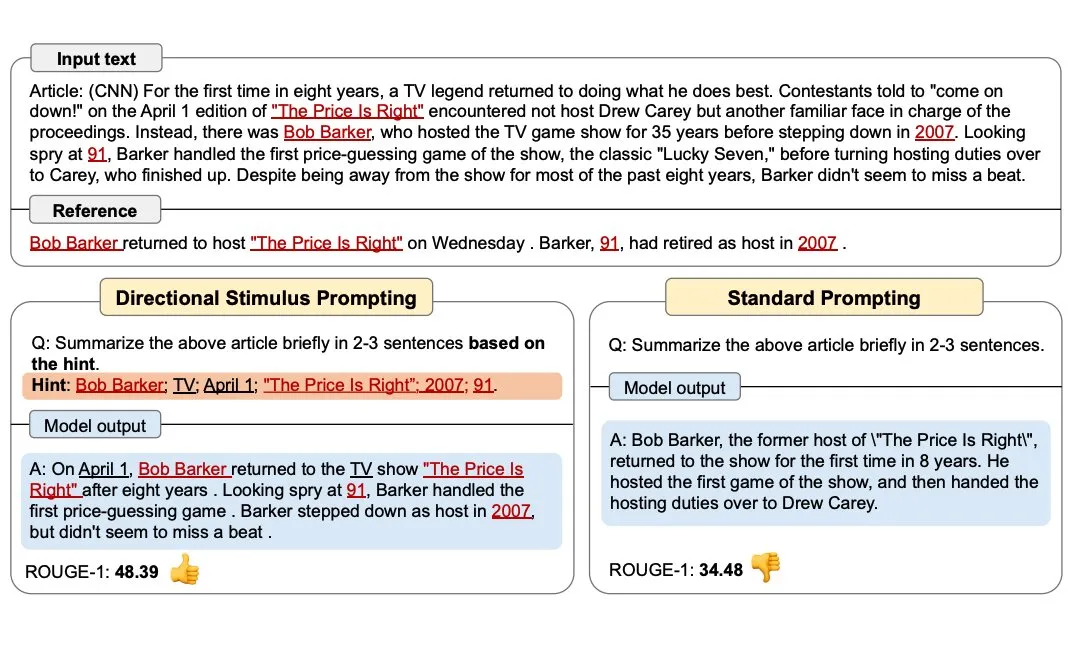
Image Source: Li et al. (2023)
The Policy Model
The policy model can be relatively small compared to the target LLM. It is optimized using Reinforcement Learning (RL) to learn how to generate the most effective hints that result in the highest quality output from the frozen model.
Why it's Effective
DSP offers a middle ground between simple prompting and full model fine-tuning:
- Efficiency: You only need to tune the small policy model, while the massive target LLM remains frozen.
- Precision: The "stimuli" act as directional anchors, ensuring the model doesn't drift during complex tasks like long-form summarization.
- Adaptability: The policy model can be quickly re-optimized for different tasks or styles without touching the core LLM's weights.
Example Use Case: In meeting summarization, a policy model might extract specific "key action items" as tokens and pass them as a stimulus. The larger LLM then uses these tokens to ensure the final summary is grounded in the most important parts of the transcript.
Directional Stimulus Prompting is part of a growing trend of using "LLMs to guide LLMs." To see how this concept evolves into fully automated instructions, explore Automatic Prompt Engineer (APE) next.